最近在 8 张 BW1100 上跑 DeepSeek-V3.2 W8A8,顺手做了一次 Profiler 分析练习。
这篇文章记录低并发 Decode、16K Prefill 和高并发 Decode 下的 kernel 时间分布,以及从这些数据里能看到什么、暂时还不能说明什么。
最近在 8 张 BW1100 上跑 DeepSeek-V3.2 W8A8,顺手做了一次 Profiler 分析练习。
这篇文章记录低并发 Decode、16K Prefill 和高并发 Decode 下的 kernel 时间分布,以及从这些数据里能看到什么、暂时还不能说明什么。
一周内,两台配置相近的 Linux 虚拟机先后出现业务无响应。控制台最后的关键日志来自 XFS:文件系统发现 inode 元数据损坏,随后主动执行 forced shutdown。
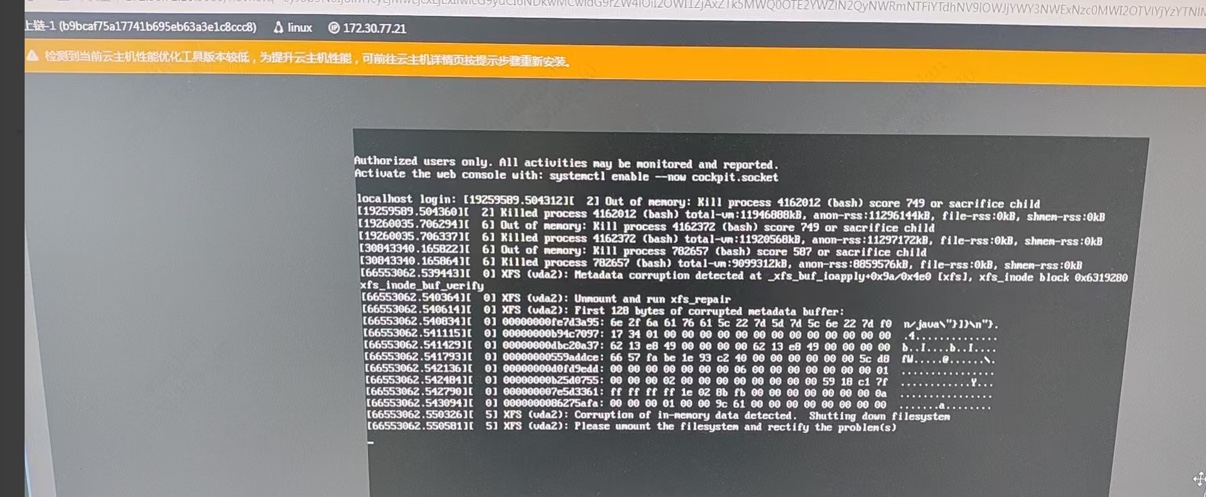
从现象上看,这很像 XFS bug、虚拟磁盘写错位置,或者底层存储损坏。但这次真正写坏 XFS 元数据的并不是 XFS。
最终定位到 Linux kernel 的 uprobe 参数抓取路径:第三方安全 Agent 注册的 uprobe 抓取了超过一页大小的参数,store_trace_args() 在边界检查前已经把数据写出 per-CPU buffer。溢出的内容落到相邻内存后,XFS write verifier 成了第一个发现损坏的组件。
换句话说,XFS 是报警的人,不是制造问题的人。
XFS 检测到元数据不符合预期时会主动关闭文件系统,防止错误继续扩大。因此,xfs_do_force_shutdown 说明 XFS 看到了损坏,但不能直接证明损坏由 XFS 产生。
面对这种问题,最开始需要同时保留几条假设:
这里最容易犯的错误,是看到 XFS 日志就只沿着文件系统代码向下查。内存损坏问题里,打印错误的函数经常只是受害者。
真正改变排查方向的是损坏数据的内容。
在异常的 inode metadata buffer 中,可以看到类似路径和 JSON 结束符的数据片段。它们不像 XFS 元数据,也不像随机 bit flip,更像某个用户态程序正在处理的字符串。
这个特征缩小了问题范围:
此时再向前检查控制台日志,可以找到 uprobe 相关 warning,并且触发进程来自第三方安全 Agent。warning、进程和损坏数据的内容开始形成同一条证据链。
uprobe 可以在用户态程序的指定地址放置探针。探针触发时,内核会读取寄存器或用户态内存中的参数,再把结果写入 tracing buffer。
相关路径使用一页大小的 per-CPU 临时 buffer。问题发生时,代码大致遵循下面的顺序:
dsize。store_trace_args() 把参数写入 ucb->buf。PAGE_SIZE。这类检查虽然存在,但没有保护作用:当检查执行时,越界写已经发生。
上游修复把检查移动到了 store_trace_args() 之前,并在长度超过一页时截断 dsize:
#define MAX_UCB_BUFFER_SIZE PAGE_SIZE |
对应的上游提交是 373b9338c972 - uprobe: avoid out-of-bounds memory access of fetching args,该问题也被登记为 CVE-2024-50067。
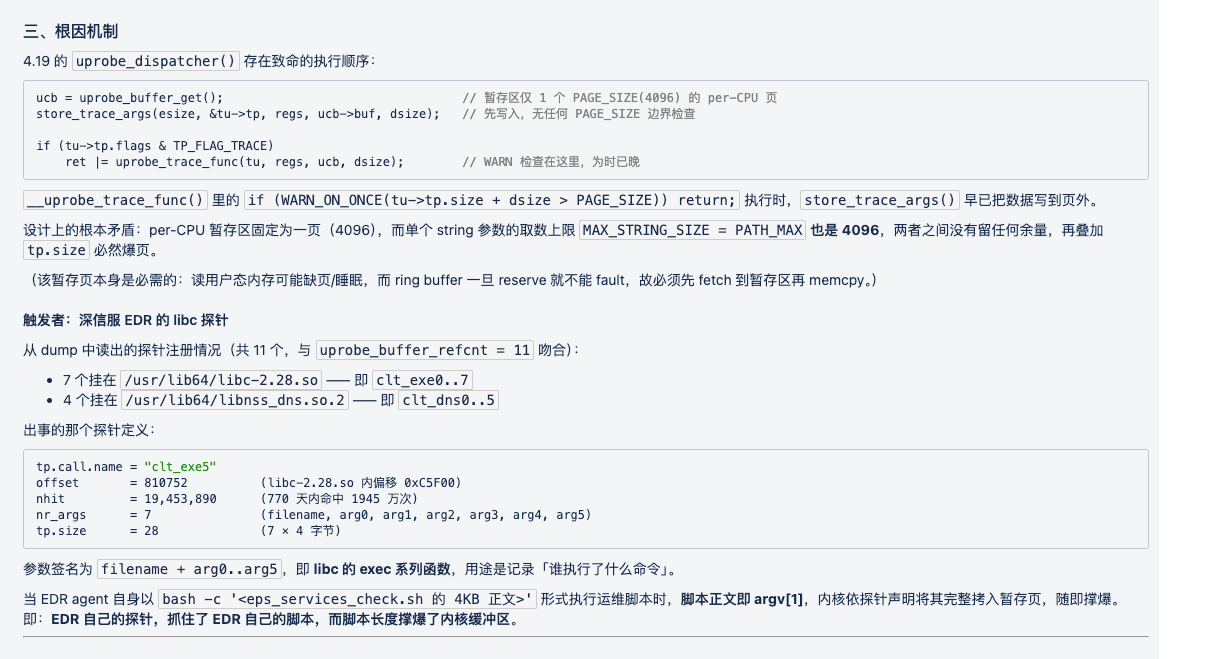
这次抓取的参数比一页 buffer 多出少量字节。这些字节不会停在 ucb->buf 的结尾,而是继续写入相邻内存。
被覆盖的内存后来作为 XFS inode metadata buffer 使用。XFS 在 write verifier 中检查 magic、字段和结构一致性时发现内容已经损坏,于是执行 forced shutdown。
目前的证据能够确认:
还有一个可以继续补强的物证:从 vmcore 中取出触发 CPU 的 uprobe_cpu_buffer 物理页,再与受损 XFS buffer 的物理页比较,确认两者在故障现场是否直接相邻。它不改变修复方向,但能把最后一段内存落点推断变成可审计的现场证据。
短期处理:
长期处理:
这次问题留下几个比较有用的排查原则。
文件系统、allocator 和 verifier 经常是最先发现内存损坏的组件。看到错误后,需要回答“谁发现了损坏”和“谁制造了损坏”两个不同的问题。
fatal error 往往出现在证据链的末端。向前读取 50 到 200 行,重点寻找 warning、异常进程名、寄存器中的长度值以及第三方模块或 tracing 事件。
不要只把损坏区域当作十六进制。尝试转成 ASCII、路径、JSON 或已知结构体。用户态字符串出现在内核元数据中,本身就是很强的方向性证据。
检查存在不等于检查有效。代码审计时必须确认长度验证是在写入之前还是之后,以及动态字符串、数组的累计长度是否可能超过固定 buffer。
当日志、数据签名、源码和上游补丁已经相互吻合时,也不要把暂未直接验证的物理页相邻关系写成既成事实。把缺口和验证方法留下来,事故结论才方便复查。
check TSC disabled from guest
1 | [ 0.000004] tsc: Detected 1999.999 MHz processor |
lscpu | grep tsc in guest, confirm cpu support tscdmidecodelscpu | grep constant_tsc in both guest and host to confirm this is not in guesttsc=reliable if need ( based on cat /proc/cmdline)lscpu if using Intel cpuacpi from libvirt. xml,but this will let all hot-plug operation failschange to using other amd cpu,tsc clocksource still could not be found
Cpu that do not has vendor intel runs linux kernel will met this issue.
method 1:
change guest os linux cmdline add tsc=reliable
method 2:
remove acpi from libvirt. xml by virsh edit
x86 guest disable constant_tsc in code,see the disscusion: https://lore.kernel.org/qemu-devel/20210426185155.G[A32439@fuller.cnet](mailto:A32439@fuller.cnet)/t/
but linux guest kernel let intel cpu use tsc and as the result intel vs amd cpu has below differences.
1 | /* |
The code defines a static integer variable tsc_unstable. The static keyword means that this variable is only visible within the file it’s defined in, limiting its scope to tsc.c. This is a common practice when you want to keep the variable private to a particular file and prevent it from being accessed directly from other files.
The __read_mostly attribute is a compiler directive specific to the Linux kernel, which suggests that this variable is expected to be read from often, but seldom written to. This can help the compiler optimize the generated code for this access pattern.
The variable tsc_unstable is used to indicate whether the TSC is unstable. The comment above the variable declaration explains that the TSC can be unstable due to CPU frequency scaling (cpufreq) or due to unsynchronized TSCs across different cores or processors.
In terms of improvements, the code is quite clear and concise. However, it might be helpful to expand the comment to explain what the implications of an unstable TSC are, and how the tsc_unstable variable is used in the system’s logic.
1 | static int __init tsc_setup(char *str) |
The __init keyword before the function name is a macro used in the Linux kernel to indicate that this function is used only at initialization time. The memory for this function is freed after the initialization is complete to conserve the kernel’s memory footprint.
Inside the function, there are several if statements that compare the input string str to different string literals using the strcmp and strncmp functions. strcmp compares two strings and returns 0 if they are identical, while strncmp compares up to a specified number of characters from two strings.
If str is “reliable”, it sets the tsc_clocksource_reliable variable to 1. If str starts with “noirqtime”, it sets the no_sched_irq_time variable to 1. If str is “unstable”, it calls the mark_tsc_unstable function with “boot parameter” as an argument. If str is “nowatchdog”, it sets the no_tsc_watchdog variable to 1.
Each of these variables or functions presumably controls a different aspect of the TSC’s behavior. For example, tsc_clocksource_reliable might indicate whether the TSC is a reliable source of time, and no_sched_irq_time might control whether the scheduler uses the TSC for interrupt timing.
In terms of improvements, the function is quite clear and concise. However, adding comments to explain the purpose of each variable and what each string argument represents would improve readability. It would also be beneficial to add error handling to account for the case where str does not match any of the expected values.
And we could use tsc=reliable to kernel cmdline to changes to tsc clock source.
1 | static void tsc_cs_mark_unstable(struct clocksource *cs) |
The function first checks if the tsc_unstable variable is already set to 1. If it is, the function immediately returns, as the TSC has already been marked as unstable. This is a common pattern in C programming known as a “guard clause”, which is used to exit a function early when certain conditions are met.
If tsc_unstable is not set to 1, the function proceeds to mark the TSC as unstable. It does this by setting tsc_unstable to 1, and then calling two functions: clear_sched_clock_stable and disable_sched_clock_irqtime. These functions presumably perform some cleanup or configuration changes related to the TSC becoming unstable.
Finally, the function logs a message using the pr_info macro, which is a kernel print function that outputs a message to the system log. The message indicates that the TSC has been marked as unstable due to the clocksource watchdog.
In terms of improvements, the function is quite clear and concise. However, adding comments to explain the purpose of the clear_sched_clock_stable and disable_sched_clock_irqtime functions would improve readability. It would also be beneficial to add error handling to account for any potential issues that could occur when these functions are called.
1 | /* |
The function begins by checking if the boot CPU has the TSC feature and if the TSC is unstable. If either of these conditions is true, the function immediately returns 1, indicating that the TSC is unsynchronized.
Next, if the system is configured for symmetric multiprocessing (SMP), the function checks if the Advanced Programmable Interrupt Controller (APIC) is clustered. If it is, the function returns 1, again indicating that the TSC is unsynchronized.
The function then checks if the boot CPU has the constant TSC feature or if the TSC clocksource is reliable. If either of these conditions is true, the function returns 0, indicating that the TSC is synchronized.
Finally, the function checks if the CPU vendor is not Intel. If it is not, and the system has more than one possible CPU, the function returns 1, indicating that the TSC is unsynchronized. If none of the previous conditions are met, the function returns 0, indicating that the TSC is synchronized.
Because of above issue, I just spent more time to check the tsc value used by guest and from host cpu do have any different. With systemtap.
value of tsc clock,average value and stantard deviation has different
and the value from guest os is not stable when compared with host
during live migration, tsc value will be smaller than usual (I think its because live migration has down time, so we need to change tsc to tolerant it)
so just from the small test, its not a good idea to relay on tsc which is not as specific as it on the host
The first version, use the script test average value and stantard deviation
in guest:
1 | TSC mean: 2000170717.800000, TSC std dev: 255861.233545 |
in guest during live migration:
1 | TSC mean: 1990107194.600000, TSC std dev: 71113321.983521 |
Samples from host:
1 | TSC mean: 2000087563.600000, TSC std dev: 16626.290598 |
TSC average value will be less that normal during migration.
change the script to check abnormal samples
1 | Sample 54, TSC diff: 1998893560, Time diff: 1000069363 ns |
just paste my test code:
1 |
|
Time Stamp Counter (TSC)All 80x86 microprocessors include a CLK input pin, which receives the clock signal of an external oscillator. Starting with the Pentium, 80x86 microprocessors sport a counter that is increased at each clock signal, and is accessible through the TSC register which can be read by means of the rdtsc assembly instruction. When using this register the kernel has to take into consideration the frequency of the clock signal: if, for instance, the clock ticks at 1 GHz, the TSC is increased once every nanosecond. Linux may take advantage of this register to get much more accurate time measurements.
Phenomenon: When creating a new virtual machine, after the virtual machine enters the “running” state (libvirt reports running, and the qemu process starts), a disk is loaded. During the kernel startup process, the disk (vdb) is recognized, and then qemu receives a device removal event, which is fed back to libvirt. Libvirt updates the XML, causing inconsistency between the disk state recorded in the zstack database and the XML on the host.
The main issue here is that the libvirt loading device interface returns success, and the XML corresponding to the device is also added. However, this device is deleted according to the event feedback from qemu.
Important log information: Here, let’s first analyze the system logs in the guest OS:
Here, we notice the logs related to pciehp because this virtual machine is UEFI-booted, leading to numerous pcie-related logs (due to UEFI boot requiring the q35 machine type, which defaults to pcie devices).
The initially observed logs include an error log from pcieport:
1 | pci 0000:00:02.7: BAR 13: failed to assign [io size 0x1000] |
Followed by the recognition of the vdb device:
1 | _virtio_blk virtio6: [vdb] 104857600 512-byte logical blocks (537 GB/500 GiB) |
An external interrupt is sent to the virtual machine:
1 | pciehp 0000:00:02.7:pcie004: Slot(0-7): Attention button pressed |
Subsequently, through ausearch, it is identified that libvirt received a device deletion event, leading to the removal of the mentioned device:
libvirt received device deleted event, removing the device
Based on these scenarios, we have summarized the steps to reproduce the issue:
Regarding the error logs mentioned above, the explanation is as follows:
pci 0000:00:02.7: BAR 13: failed to assign [io size 0x1000]:
_virtio_blk virtio6: [vdb] 104857600 512-byte logical blocks (537 GB/500 GiB):
pciehp 0000:00:02.7:pcie004: Slot(0-7): Attention button pressed:
As for the key QEMU code, by searching the codebase, it has been confirmed that QEMU sends the corresponding interrupt when resetting the PCIe slot, and the host prints the log as part of the corresponding processing logic.
code from pcie.c
1 | pci_word_test_and_clear_mask(exp_cap + PCI_EXP_SLTSTA, |
which is used in qdev.c
1 | QLIST_FOREACH(bus, &dev->child_bus, sibling) { |
During the device hotplug process, there will be a reset action.
Kernel-related code:
from pciehp_hpc.c
1 | static int pciehp_poll(void *data) |
This code represents a kernel function for polling PCIe Hot Plug events. It uses a kernel thread (kthread) to continuously poll for interrupt events or user requests related to PCIe Hot Plug. The function includes a timeout mechanism with an initial delay of 10 seconds and then repeats the polling process based on the specified polling time. The function stops when the kernel thread should stop (kthread_should_stop() returns true).
And pciehp_handle_button_press is implemented as following:
1 | void pciehp_handle_button_press(struct controller *ctrl) |
Both OFF_STATE and ON_STATE could changed to each other by same press request.
Based on the test results, we preliminarily conclude that there is a race condition between hot-plug operations and kernel boot, leading to unexpected changes in the PCIe slot’s state from off → on → off. (Note: The crucial point here is that pciehp_handle_button_press(ctrl); simultaneously handles both on and off scenarios.)
With reference to the above keywords, we identified a related Bugzilla entry for QEMU version 4.2 by searching for ‘qemu pci device kernel boot race condition’:
https://bugzilla.kernel.org/show_bug.cgi?id=211691
“The document mentions a virtio-net failover mechanism introduced by QEMU 4.2, addressing the issue of hot-plugging network cards failing during the VM startup phase. This problem arises from a race condition in the QEMU code that sets the PCIe slot’s state. The provided QEMU patch resolves the issue:
The title of this patch is: ‘pcie: don’t set link state active if the slot is empty.’
Upon reviewing its content, it appears that during PCIe initialization and the hot-plug phase, the ‘reset’ is called, potentially causing inconsistencies in the slot’s state. This patch addresses the problem by preventing the setting of the link state to active if the slot is empty, eliminating the observed issue.”
TIPs:
Search for changes related to the virtual machine process using ausearch:
1 | ausearch -m "VIRT_RESOURCE" -p 63259 |
Libvirt’s XML and QEMU event update mechanism: Details can be found in TIC-1360 - Cloud VM disk does not exist, capacity inconsistency between UI interface and underlying view (Closed).
Quick reference for PCIe events:
From linux pci_regs.h:
1 |
QEMU systemtap trace, refer to: QEMU Tracing Documentation
1 | /usr/bin/qemu-trace-stap run /usr/libexec/qemu-kvm pci_cfg_write |
Guest os pcie trace analysis:
1 | [一 12月 4 15:06:48 2023] pciehp 0000:00:02.7:pcie004: pending interrupts 0x0010 from Slot Status |
cmd 0x0100
1 | #define PCI_EXP_SLTCTL_PWR_IND_ON 0x0100 /* Power Indicator on */ |
[一 12月 4 15:06:48 2023] pciehp 0000:00:02.7:pcie004: pciehp_set_attention_status: SLOTCTRL 6c write cmd c0
cmd 0x00c0
0000 0000 1100 0000
1 | #define PCI_EXP_SLTCTL_ATTN_IND_BLINK 0x0080 /* Attention Indicator blinking */ |
[一 12月 4 15:06:48 2023] pciehp 0000:00:02.7:pcie004: pciehp_green_led_blink: SLOTCTRL 6c write cmd 200
cmd 0x0200
1 | #define PCI_EXP_SLTCTL_PWR_IND_BLINK 0x0200 /* Power Indicator blinking */ |
[一 12月 4 15:06:48 2023] pciehp 0000:00:02.7:pcie004: pciehp_set_attention_status: SLOTCTRL 6c write cmd c0
cmd 0x00c0
0000 0000 1100 0000
1 | #define PCI_EXP_SLTCTL_ATTN_IND_BLINK 0x0080 /* Attention Indicator blinking */ |
[一 12月 4 15:06:53 2023] pciehp 0000:00:02.7:pcie004: pciehp_power_off_slot: SLOTCTRL 6c write cmd 400
cmd 0x0400
1 | #define PCI_EXP_SLTCTL_PWR_OFF 0x0400 /* Power Off */ |
[一 12月 4 15:06:54 2023] pciehp 0000:00:02.7:pcie004: pciehp_green_led_off: SLOTCTRL 6c write cmd 300
cmd 0x0300
1 | #define PCI_EXP_SLTCTL_PWR_IND_OFF 0x0300 /* Power Indicator off */ |
The physical layout of CPU cores in a system is known as CPU topology. Understanding CPU topology can significantly impact the performance of a system, as it determines the effectiveness and efficiency of the cores.
CPU topology comprises three primary levels:
The CPU topology can be described using a tree-like structure, with the socket level at the top and the thread level at the bottom. The cores in a socket are connected to each other via a bus, and the threads in a core are connected to each other by a shared cache.
Understanding CPU topology is crucial for improving system performance. The topology can be used to optimize the performance of a system by assigning threads to cores in a way that minimizes the amount of communication between cores. This can enhance the performance of applications that are heavily multithreaded.
Additionally, the CPU topology can be used to troubleshoot performance issues. For example, if an application is running slowly, the CPU topology can be used to identify which cores are being used the most. This information can help identify the source of the performance problem and take appropriate steps to improve it.
Here are some benefits of understanding CPU topology:
There are several tools available to display CPU topology, and one of the most commonly used tools is lscpu. Here is an example of using lscpu to display CPU topology:
1 | [root@172-20-1-220 ~]# lscpu |
hwloc-ls
1 | [root@172-20-1-220 ~]# hwloc-ls |
Virtual machines (VMs) are software programs that create an isolated environment for running operating systems and applications. VMs are often used to run various operating systems on the same physical machine or to run applications that require more resources than are available on the host machine.
When a VM is created, the hypervisor, which manages the VMs, assigns a single thread to the VM. This is because assigning multiple threads to a VM can lead to performance issues. Threads share the same resources on a core, and multiple threads can compete for resources, leading to contention and slowdowns. Furthermore, threads may interfere with each other, causing further slowdowns.
To optimize VM performance, it’s generally best to assign a single thread to a VM. However, there are exceptions to this rule. For example, if a VM is running an application that is specifically designed to take advantage of multiple threads, it may be beneficial to assign multiple threads to the VM.
To take advantage of multiple threads in a virtual machine, it’s essential to use a hypervisor that supports thread pinning, an operating system that supports thread scheduling, and an application that is designed to take advantage of multiple threads. Multithreaded applications such as web servers, database servers, and media transcoders are good examples of applications that can take advantage of multiple threads.
There are two main reasons why the number of threads in a CPU topology is usually limited to 1 or 2:
In some cases, having more than two threads per core may be beneficial. For instance, heavily multithreaded applications may take advantage of the extra threads. However, in most cases, the costs of having more than two threads per core outweigh the benefits.
There are a few exceptions to the rule that the number of threads in a CPU topology is usually limited to 1 or 2. For example, some CPUs support hyper-threading, which allows a single core to run two threads simultaneously. However, hyper-threading is not always a good idea, as it can sometimes lead to performance degradation.
Overall, the number of threads in a CPU topology is usually limited to 1 or 2 due to physical constraints and scheduling overhead. While there are exceptions, in most cases, the costs of having more than two threads per core outweigh the benefits.
Sockets and cores do have an impact on performance.
However, it’s important to note that the number of sockets and cores is not the only factor that affects performance. Other factors, such as the clock speed of the CPU, the amount of cache memory, and the type of memory, can also have a significant impact.
In general, systems with more sockets and cores will have better performance than systems with fewer sockets and cores. However, it’s important to choose a system that has the right balance of sockets, cores, clock speed, cache memory, and memory type for your needs.
Here are some examples of how sockets and cores can impact performance:
There are a few reasons why cloud providers like AWS do not offer multi-socket instances.
For these reasons, cloud providers like AWS choose to offer single-socket instances. Single-socket instances are less expensive, easier to manage, and offer the same or better performance than multi-socket instances.
However, there are some cases where multi-socket instances may be a good choice. For example, if you need a lot of CPU power, or if you need to run applications that are not well-optimized for multi-threading, then a multi-socket instance may be a good option.
If you are considering using a multi-socket instance, it is important to weigh the costs and benefits carefully. You should also make sure that your applications are well-optimized for multi-threading.